AI Engineering // Security // Governance

Practical AI security and policy for systems that act

Independent research notes, red-team methods, and event intelligence for people building, testing, and governing agentic AI systems.

Calendar

Upcoming events

Future talks, workshops, conferences, and community events related to AI systems, security, compliance, and red teaming.

Featured Reading

Current material worth reading

Technical guides, hands-on exercises, and detailed implementation write-ups for testing and securing AI systems in practice.

Outcome-graded agents: make completion criteria explicit and inspect the grader video thumbnail Play video
AI Engineer October 12, 2026 video

Outcome-graded agents: make completion criteria explicit and inspect the grader

The Managed Agents research-desk workshop turns a requested deliverable into an explicit rubric and an iterative evaluation loop. Anthropic’s documentation describes a grader with a separate context window, per-criterion feedback, and events for inspecting the result. Separating the grader’s context can reduce direct influence from the worker’s reasoning, but a satisfied rubric still does not establish that every fact or source in the artifact is correct.

Managed agents: version configuration and verify tenant boundaries video thumbnail Play video
AI Engineer October 12, 2026 video

Managed agents: version configuration and verify tenant boundaries

This workshop Q&A covers configuration in CI/CD, long-running tools, and resource separation for customer-facing agents. Current documentation treats agent definitions as versioned resources and metadata as tracking fields. Labelling a session with a customer ID is not an authorization boundary. A deployment needs deliberate credential and resource separation, and self-hosted execution also requires the operator to supply its own sandbox controls.

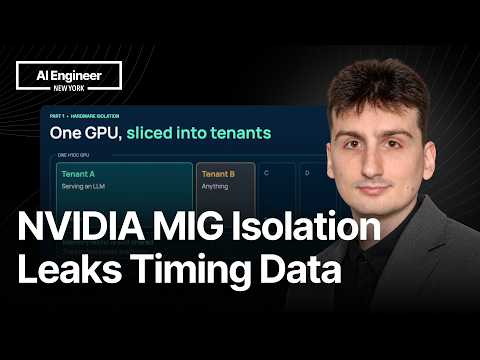
Shared-GPU timing research: distinguish isolation from workload confidentiality video thumbnail Play video
AI Engineer October 12, 2026 video

Shared-GPU timing research: distinguish isolation from workload confidentiality

Branislav Brzak describes timing measurements that infer model and workload characteristics on tested H100 configurations. Stealthium’s primary research explains how memory-barrier behavior can cross MIG partitions and how a weaker cross-GPU signal depends on device visibility and allocation permissions. Workload classification in the follow-up requires speculative decoding. The demonstrated signal does not recover the actual prompt or generated answer.

From Code to Intelligence: The Rise of the Full-Stack AI Engineer - Adam Stephensen - NDC Oslo 2026 video thumbnail Play video
NDC Conferences YouTube October 12, 2026 video

From Code to Intelligence: The Rise of the Full-Stack AI Engineer - Adam Stephensen - NDC Oslo 2026

This talk was recorded at NDC Oslo in Oslo, Norway. #ndcoslo #ndcconferences #developer #softwaredeveloper Attend the next NDC conference near you: https://ndcconferences.com https://ndcoslo.com/ Subscribe to our YouTube channel and learn every day: / @NDC Follow our Social Media!

Sponsored Liquid Learn AI governance health check Understand your AI readiness before the next review. Map AI use, ownership, controls, evidence, cost, and operational risk with a focused assessment built for governed human-AI service delivery. 24 focused questions Readiness score PDF report Open health check -> liquidlearn.ai/assessment
Latest Notes

New additions to the research library

Recent notes and references across prompt injection, agent security, evaluations, responsible AI, and adjacent AI work.

Sandbox testing: turn generated workflows into reproducible failure cases video thumbnail Play video
AI Engineer October 12, 2026 video

Sandbox testing: turn generated workflows into reproducible failure cases

Kevin Orellana describes using a coding agent through an MCP wrapper to exercise sandbox and browser workflows, storing results in a structured database. Reported failures include encoding, file handling, and resource exhaustion. The useful testing pattern separates interface defects from execution limits and preserves a reproducible case for each finding. An agent-generated test count is not evidence of coverage, and a passing test does not prove containment.

auth.md reference flow: verify identity, consent, and credential revocation video thumbnail Play video
AI Engineer October 12, 2026 video

auth.md reference flow: verify identity, consent, and credential revocation

Michael Grinich introduces auth.md, a proposal for agent registration backed by public provider and service examples. The reference flow separates identity assertion, user claim or consent, and credential issuance, with issuer, audience, freshness, and replay checks. It also documents a hazard when the same credential gains permissions after an anonymous registration is claimed. This is an evolving reference implementation, not an established universal signup standard.

Scheduled agents: separate future triggers, active sessions, and memory changes video thumbnail Play video
AI Engineer October 12, 2026 video

Scheduled agents: separate future triggers, active sessions, and memory changes

This Managed Agents workshop combines scheduled execution, session fan-out, and a research preview for memory updates. Current deployment documentation makes an operational distinction: pausing a schedule suppresses future automatic triggers while existing sessions continue and manual runs remain possible. Per-run budgets are separate caps, not a lifetime spending limit. The memory preview is not evidence of safe or reliable autonomous improvement.

Agent authorization: human approval must stay within the user’s authority video thumbnail Play video
AI Engineer October 12, 2026 video

Agent authorization: human approval must stay within the user’s authority

Kim Maida contrasts an overprivileged triage agent with a staged workflow that carries user identity through delegated access and evaluates policy before tool actions. OAuth token exchange provides a mechanism for requesting downstream credentials; the security token service and resource still determine permitted access. The talk’s intent-based authorization design is a proposal. Neither a human approval button nor a short-lived token makes an unauthorized action legitimate.

Topic Coverage

Prompt engineering, AI compliance, agent security, and more

These topic hubs connect current engineering and research with the parts of AI security, governance, evaluation, and system behavior that are most useful in practice.

AI Red Teaming

Methods, case studies, and tooling for red teaming AI systems end to end.

Open topic
Prompt Engineering

Prompt design patterns, instruction hierarchy, and defensive prompt construction.

Open topic
Prompt Injection

Prompt injection attacks, mitigations, detection, and design patterns for safer AI applications.

Open topic
Agent Security

Controls and attack paths for browsing, tool use, memory, identity, and action-taking agents.

Open topic
Model Evaluation

Safety evaluations, system cards, preparedness, and security measurement for frontier models.

Open topic
AI Compliance

Responsible AI, governance, standards, and regulatory reference material for teams mapping AI systems to policy and operational controls.

Open topic
Adversarial ML

Adversarial machine learning attacks, taxonomies, and mitigations across the ML lifecycle.

Open topic
AI Engineering

Application architecture, developer workflow, tooling, and production patterns for building AI systems.

Open topic
Profile

Profile and contact

Focused on AI engineering, responsible AI, compliance, model behavior, and operational AI systems. Current work includes founding AI operational software for compliance and financial tracking.